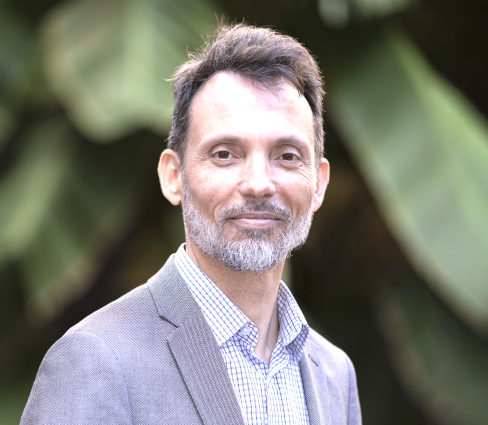
Professor José Hernández-Orallo

PhD in Logic and Philosophy of Science (Extraordinary Prize), MSc in Computer Science (Erasmus from UPV), BSc in Computer Science

Co-lead at CAPAIBLE Lab, Kinds of Intelligence Programme, Leverhulme CFI Associate Fellow at the Centre for Human-Inspired AI (CHIA) at the Institute of Technology and Humanity

Professor José Hernández-Orallo

About me

José’s work focuses on how we measure intelligence across machines, people, and the hybrid systems that see an intersection between the two. He is interested in what current AI can and cannot do, how to evaluate those capabilities rigorously, and what they mean for the risks and opportunities ahead. He founded the AI Evaluation newsletter (opens in a new tab) and AI Evaluation Programme (opens in a new tab), and his work in this area has been covered by The Economist, the Wall Street Journal, the Financial Times, New Scientist, and the BBC.

Courses

Awards

2022: Blue Sky Best Paper Runner-up Award, Computing Community Consortium (CCC), Association for the Advancement of AI

2021: European Association for Artificial Intelligence (EurAI) Fellow

2018: PROSE Award (opens in a new tab) for the book ‘The Measure of All Minds’

2016: Best Paper Award and Best Paper Runner-up Award, 18th European Conference on Artificial Intelligence (ECAI)

Publications

Hernández-Orallo, J. et al (2026). General scales unlock AI evaluation with explanatory and predictive power (opens in a new tab). Nature, 652, 58–67.

Hernández-Orallo, J. et al (2026). The science and practice of proportionality in AI risk evaluations (opens in a new tab). Science, 391(6787), 769–771.

Hernández-Orallo, J. et al (2025). Personalized safety in LLMS: A benchmark and a planning-based agent approach (opens in a new tab). arXiv, cs.CY.

Hernández-Orallo, J. et al (2024). Larger and more instructable language models turned less reliable (opens in a new tab). Nature. 634, 61–68.

Hernández-Orallo, J. et al (2024). Melting pot contest: Charting the future of generalized cooperative intelligence (opens in a new tab). In NIPS ’24: Proceedings from the 38th Conference on Neural Information Processing Systems Track on Datasets and Benchmarks, 517, 16213–16239.

Hernández-Orallo, J. et al (2024). Foundational challenges in assuring alignment and safety of large language model (opens in a new tab). Transactions of Machine Learning Research.

Hernández-Orallo, J. et al (2023). Rethink reporting of evaluation results in AI: Aggregate metrics and lack of access to results limit understanding (opens in a new tab). Science, 380(6641), 136–138.

Hernández-Orallo, J. et al (2023). Your prompt is my command: On assessing the human-centred generality of multimodal models (opens in a new tab). Journal of Artificial Intelligence Research, 7, 377–394.

Hernández-Orallo, J. et al (2022). Not a number: Identifying instance features for capability-oriented evaluation (opens in a new tab). In IJCAI ’22: Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, 2827–2835.

Hernández-Orallo, J. et al (2022). Training on the test set: Mapping the system-problem space in AI (opens in a new tab). In AAAI ’22: 36th Conference of the Association for the Advancement of Artificial Intelligence, 36(11), 12256–12261.

Roles

Founder and Director of the AI Evaluation newsletter (opens in a new tab) and AI Evaluation Programme (opens in a new tab).

Member of the Association for the Advancement of Artificial Intelligence (AAAI)

Member of the Confederation of Laboratories for Artificial Intelligence Research in Europe (CAIRNE)

Member of the European Laboratory for Learning and Intelligent Systems (ELLIS)

EurAI Fellow

Member of the EU AI Office scientific panel